01Aug 2026
doc-unify
FastAPIPythonTypeScriptOllamapgvectorDocker
Overview
An offline-first document intelligence microservice that ingests heterogeneous PDF, image, DOCX, and PPTX files, builds a vector index in Postgres (pgvector), automatically proposes a unified schema across the corpus, and extracts structured records with cell-level provenance and confidence scores.
Approach
- Built multi-format ingestion pipelines for PDF, scans, docx, and pptx with OCR fallback, chunked and embedded locally into Postgres with pgvector.
- Clustered candidate fields across heterogeneous documents into a unified schema, with a local LLM reviewing cluster boundaries and flagging semantic ambiguities.
- Engineered automated extraction against the approved schema with unit/scale normalization, per-cell confidence scoring, and an interactive review queue for un-reconciled fields.
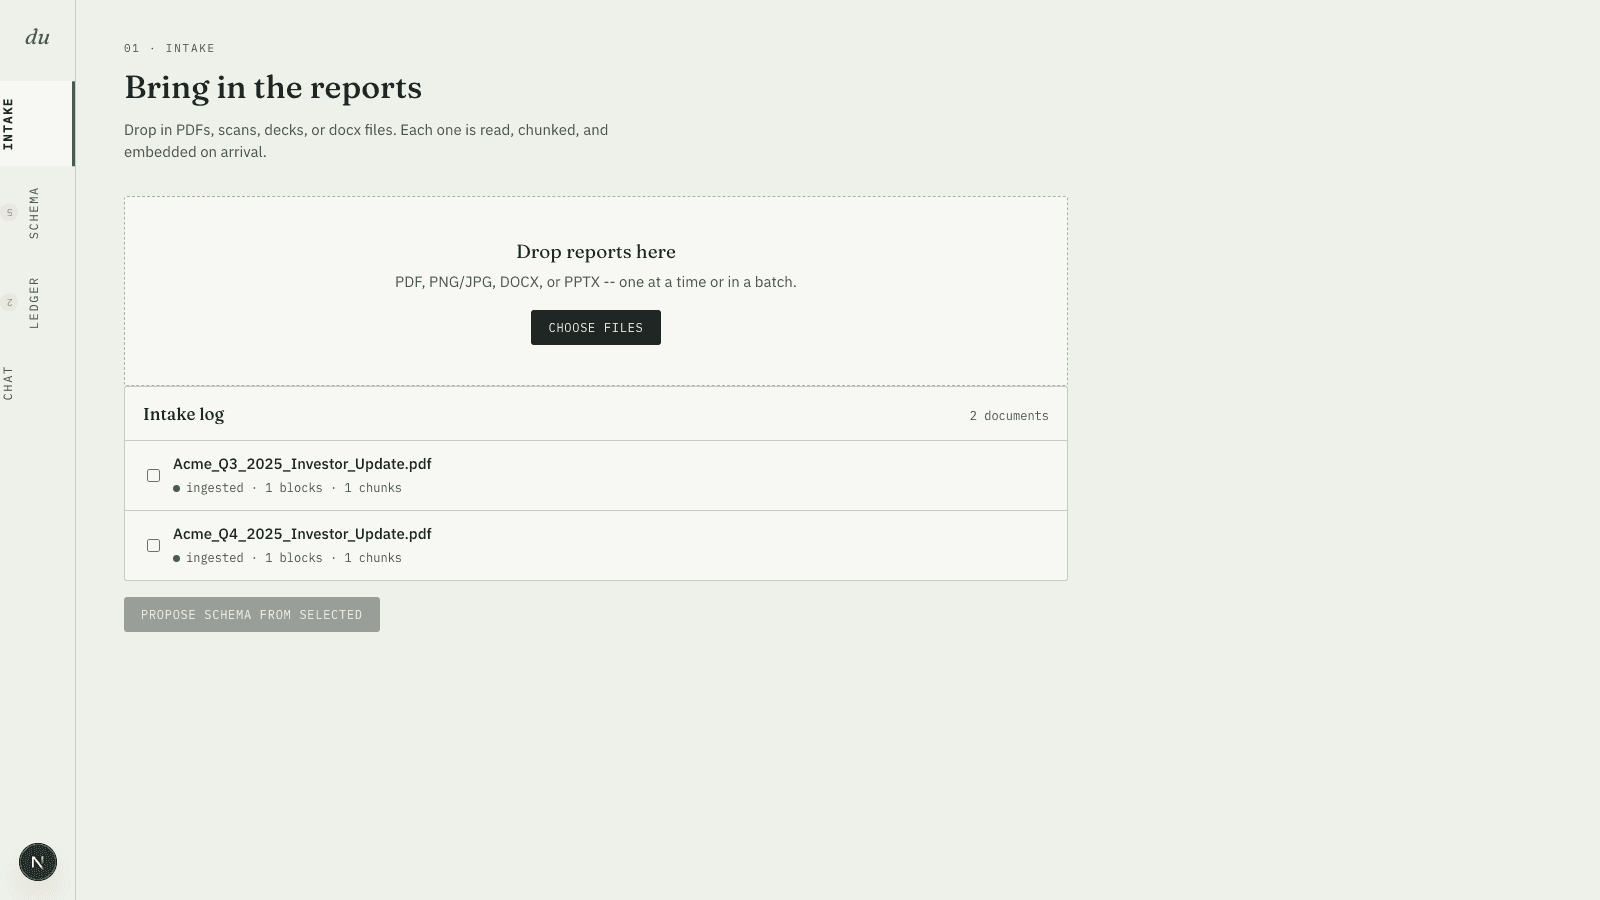
doc-unify intake screen: documents being ingested, chunked, and embedded
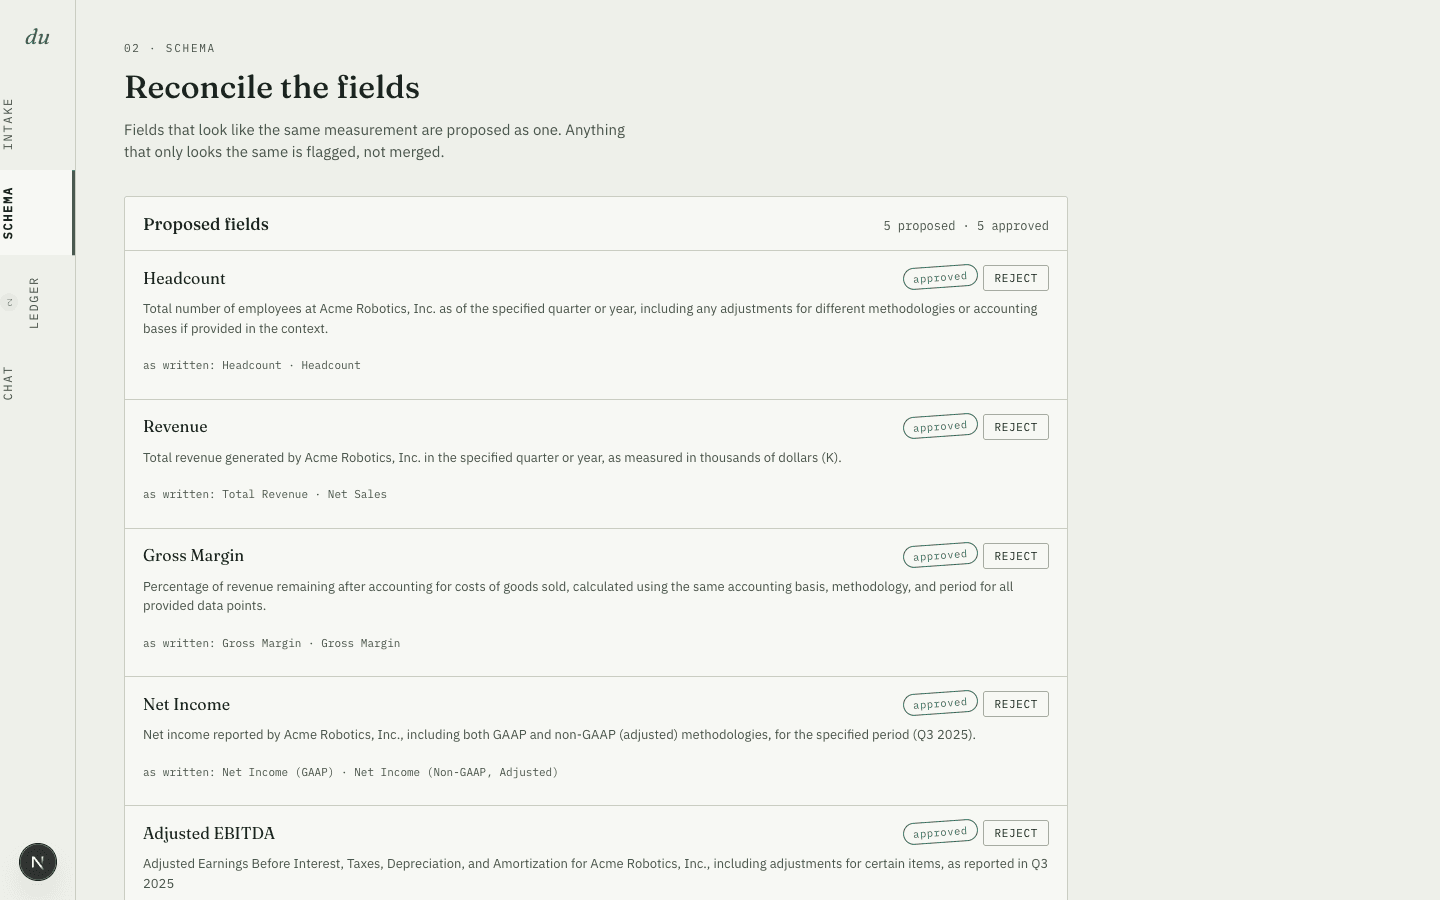
doc-unify schema screen: candidate fields clustered into a proposed unified schema
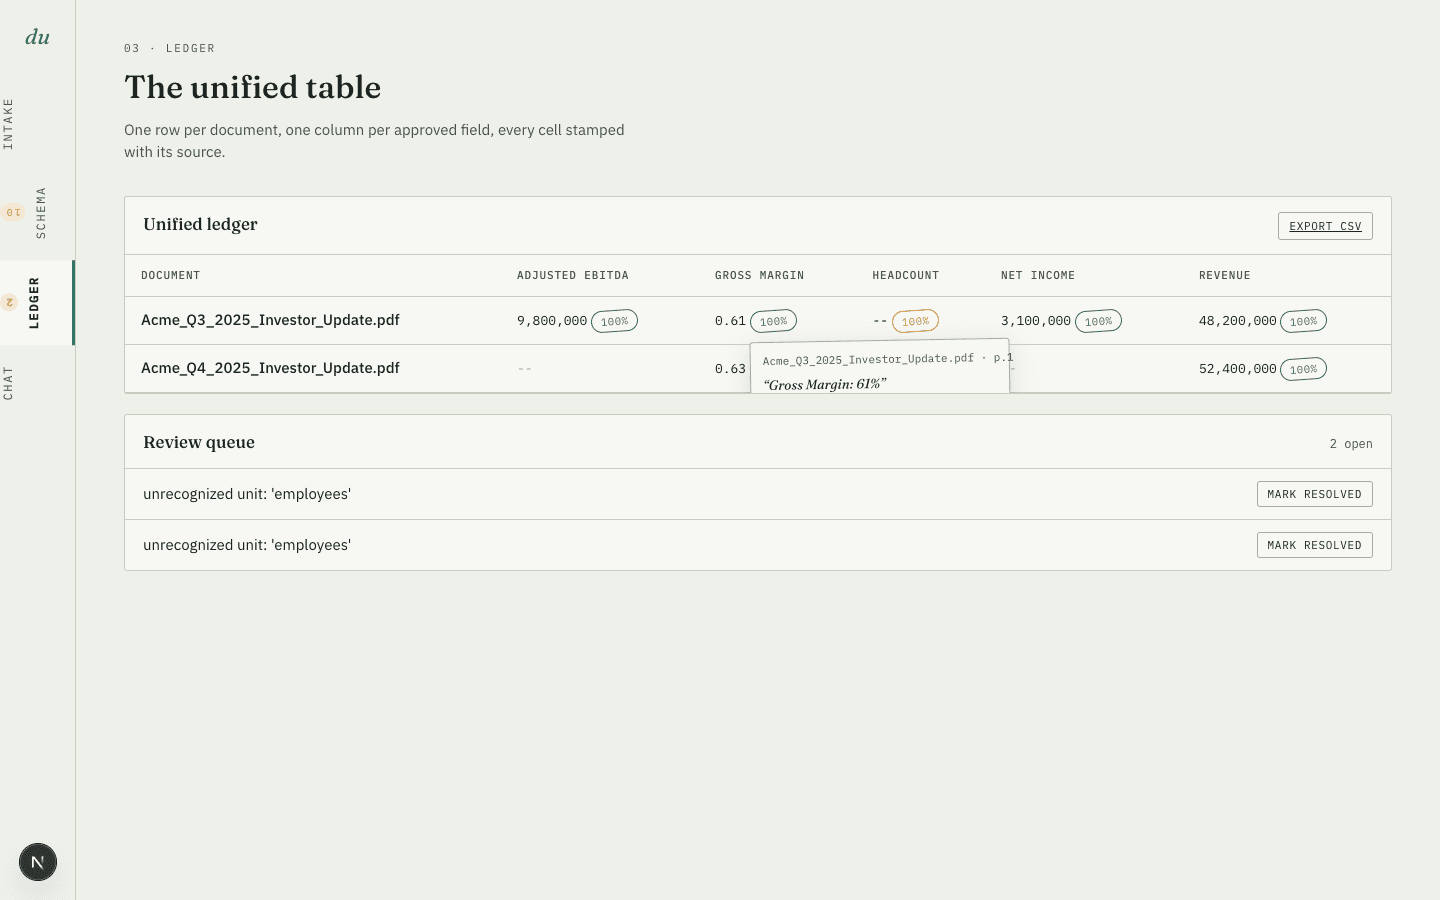
doc-unify ledger screen: the unified table with per-cell confidence and source citations
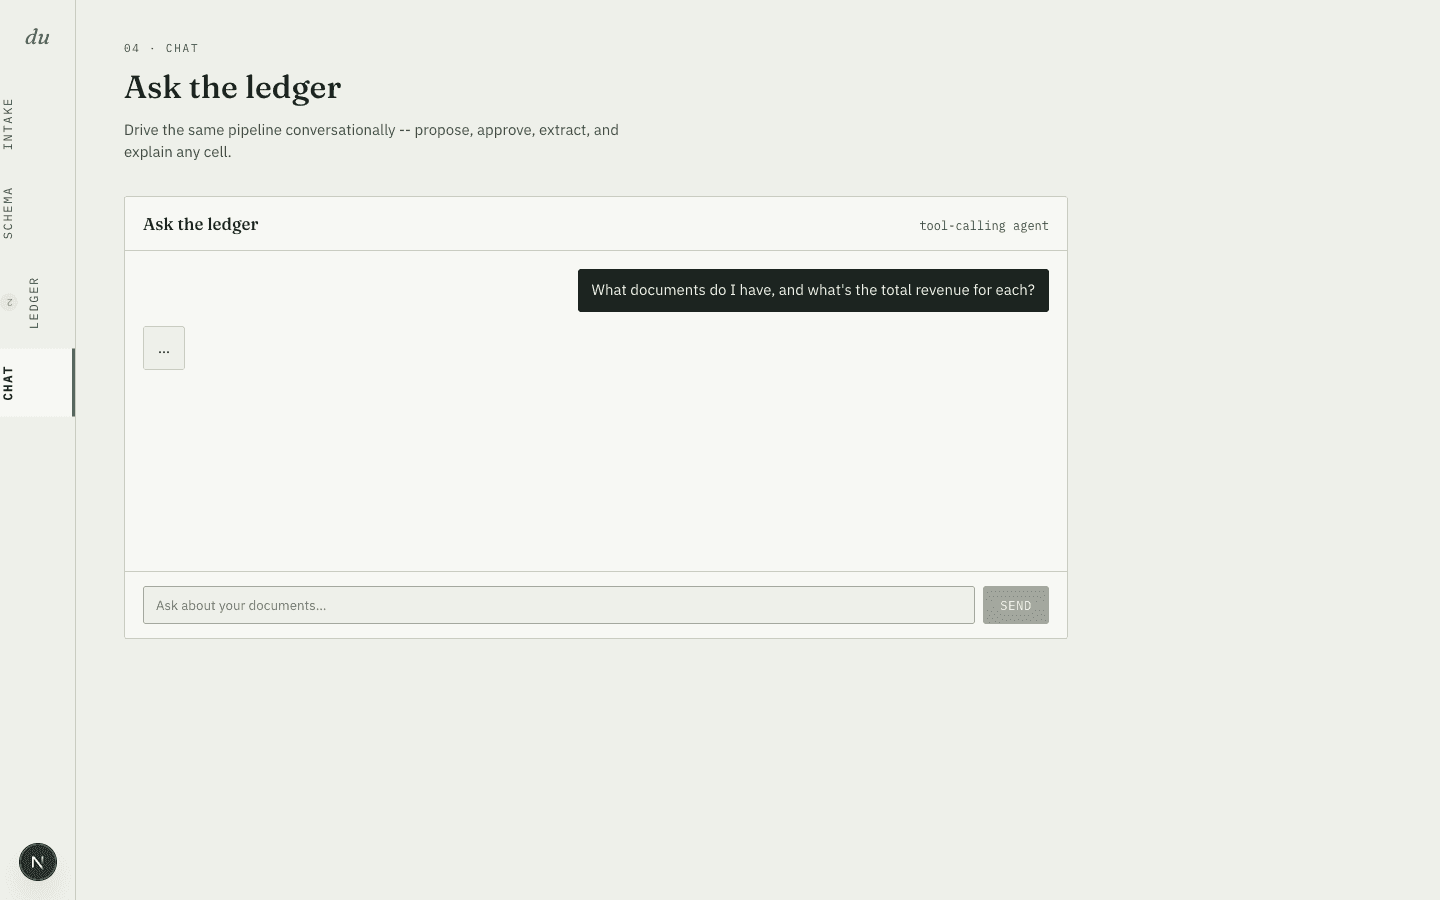
doc-unify chat screen: querying the pipeline conversationally through a tool-calling agent
Results
Metrics — sourced from the repo (README / model card / test output)
- Backend tests
- 79 passing
- Lint
- ruff clean
- Pipeline stages
- 4 (ingest → schema → extract → chat)
- External API calls
- 0
fully offline via Ollama; 1 env var to point at a hosted model
Runs entirely offline on local models — Ollama for LLM and embeddings, zero external API dependencies. Pointing to hosted cloud models is a single environment configuration change. 79 backend tests passing.
Impact